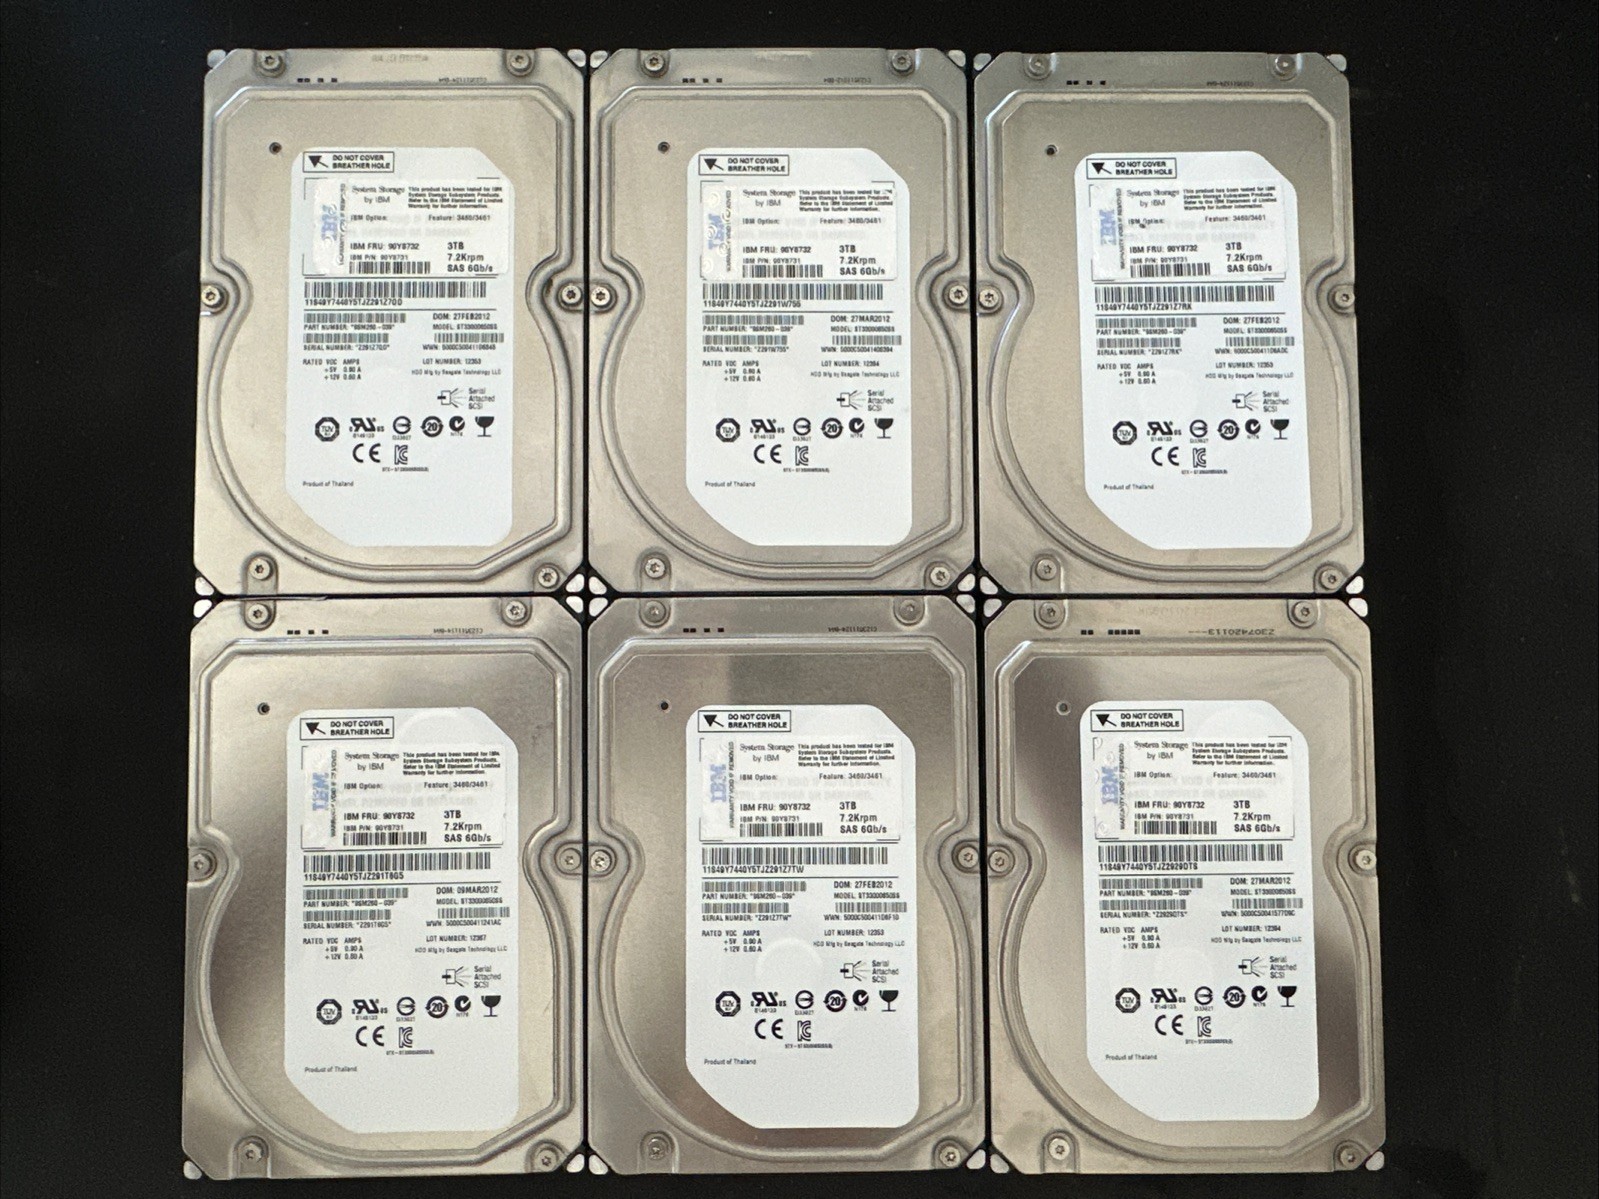
SEAGATE ST33000650SS 3TB 7200 RPM SAS 3.5-INCH ENTERPRISE HARD DRIVELOT OF 6 - CONSTELLATION ES.2 - IBM FIRMWARE
READ THIS FIRSTThese drives have roughly 6.9 years of power-on time each - 59718 to 60851 hours. That is the highest mileage of anything we sell and the range is in the title. They are priced as high-hour drives. What they have going for them is that all six came out of one array, all six read zero grown defects and zero uncorrected errors, and all six held those numbers through a complete 3 TB write. There is one thing in their logs you should read about before you buy, and it is in the section headed THE BACKGROUND SCAN LOG below.
THESE REPORT AS IBM, NOT SEAGATEThe drive is a Seagate Constellation ES.2. The vendor string burned into it is IBM-ESXS and the firmware is BC3B, because these shipped inside IBM equipment. smartctl will show you Vendor: IBM-ESXS, Product: ST33000650SS. They are standard 512-byte-sector SAS drives and are not locked to IBM hardware, but if your tooling or your array expects a retail Seagate vendor string, know this going in.
WHAT THE SMART DATA ACTUALLY SAYS
Serial Z2929DTS00009233EPTQ - 59718 hours - grown 0 - uncorrected 0/0/0 - non-medium 949 - rewrite-in-place events 210 - 689 TB read - 289 TB writtenSerial Z291T6G500009230A6YJ - 60248 hours - grown 0 - uncorrected 0/0/0 - non-medium 289 - rewrite-in-place events 48 - 490 TB read - 52 TB writtenSerial Z291W75500009232LKM3 - 60742 hours - grown 0 - uncorrected 0/0/0 - non-medium 412 - rewrite-in-place events 276 - 685 TB read - 290 TB writtenSerial Z291Z7TW000092170LSY - 60763 hours - grown 0 - uncorrected 0/0/0 - non-medium 639 - rewrite-in-place events 265 - 494 TB read - 52 TB writtenSerial Z291Z7QD00009230A1Q3 - 60839 hours - grown 0 - uncorrected 0/0/0 - non-medium 90 - rewrite-in-place events 548 - 509 TB read - 73 TB writtenSerial Z291Z7RK00009219UJ74 - 60851 hours - grown 0 - uncorrected 0/0/0 - non-medium 36 - rewrite-in-place events 9 - 507 TB read - 73 TB written
Every drive above: SMART health OK, firmware BC3B, 512-byte sectors, 7200 RPM, 6 Gb/s negotiated link rate read from the drive's own phy log.
THE BACKGROUND SCAN LOG - THE PART MOST SELLERS DO NOT SHOW YOURun smartctl on these and you will see background scan entries that read "Recovered via rewrite in-place" with sense code 1,18,7. The counts are listed per drive above and they range from 9 to 548.
Here is what that actually means. The drive runs a background media scan. If it finds a sector that needed error correction to read back, it rewrites that sector in place and re-checks it. If the sector then passes, the drive keeps using it and does NOT consume a spare. That is why the grown defect list on every one of these six still reads 0 - nothing had to be permanently reallocated. It is the drive doing preventive maintenance on marginal media, which is what a 60000-hour enterprise drive is supposed to do.
Here is why we are not worried about it, and you can check our reasoning. We captured the full SMART state before the wipe and again after. Then we wrote zeros to every one of the 3 TB. A full-surface write is the single best test for weak sectors, because every block has to accept a write. Afterwards:
- grown defects: 0 before, 0 after, on all six- uncorrected errors: 0 before, 0 after, on all six- non-medium errors: identical before and after, on all six- rewrite-in-place events: identical before and after, on all six
Not one new event on any drive. If this media were actively degrading, a full 3 TB write is where it would have shown up. It did not.
We are still telling you the number, because a buyer who runs smartctl on arrival will see it and should not be surprised by it.
ABOUT THE NON-MEDIUM ERROR COUNTSNon-medium errors run 36 to 949 across these drives. A non-medium error is a bus or interface event - a reset, an aborted command, a loss of dword synchronization - and not a media defect. Counts in the hundreds are ordinary for a drive that spent 6.9 years on a shared SAS backplane. These counters also did not move during the wipe.
HOW WE TESTEDEach drive was catalogued with smartctl before anything was written to it, then given a full-length zero overwrite of every logical block with dd until the device reported end-of-media, then catalogued again. We keep both captures and the per-drive wipe log.
HONEST ASSESSMENTThese are old, high-hour, heavily-read enterprise drives - some have over 680 TB read on them. Buy them for bulk capacity in a lab, for a scratch or backup array, for cold spares, or for anything where you have redundancy and the hours do not frighten you. Do not buy them as your only copy of anything, and do not buy them expecting years of remaining service life. They test clean today and we have documented exactly how clean and exactly where the wear shows. That is the whole pitch.
INTERFACE NOTEThese are SAS drives. They will NOT work in a SATA port. You need a SAS controller or backplane.
DATA SANITIZATIONEvery logical block on every drive was overwritten with zeros. We then read back the start, middle and end of each drive and confirmed every byte was zero - the wipe log for each drive records head, middle and tail non-zero byte counts of 0. All six arrive fully zeroed with no partition table.
WHAT YOU GETSix (6) bare 3.5-inch SAS hard drives, the exact serials listed above. No caddies, no trays, no rails, no screws, no cables, no adapters.
WARRANTYOut of warranty. No manufacturer support.
SOLD AS-ISSold as-is with no returns. Everything we measured is printed above. If you need a reading we did not capture, ask before buying.